Quantization Guide: How to Balance Speed and Accuracy 1
This article is about Quantization. "The gap between raw computing power and model intelligence is narrowing, but the physical limits of hardware remain the ultimate bottleneck."
If you are running large language models on consumer-grade hardware, understanding the relationship between bit-depth and performance is essential for stability.
This guide explores how quantization affects model intelligence, why low-bit precision can cause system crashes, and how to balance efficiency with accuracy.
Key Takeaways * Quantization reduces model size but can lead to subtle or significant intelligence loss. * Insufficient precision can cause system instability or complete software failure. * Hardware constraints often dictate the practical limits of model deployment.
* Choosing the right bit-depth is a trade-off between speed and reasoning capability.
Why does low precision cause system crashes?
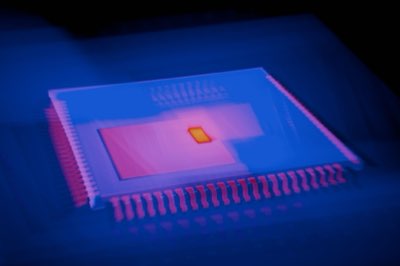
At midnight in the silent office, a sudden heat radiates from the tower as the system freezes during a botched quantization.
A developer sits at a desk, staring at a frozen terminal screen after attempting to load a massive model on a single workstation. The cooling fans spin at maximum velocity, but the screen remains unresponsive.
According to the Open Software Foundation, the merger of X/Open and the Open Software Foundation in 1996 helped shape the industry standards used in modern computing environments.
When the bit-depth is set too low, the mathematical operations required to run the model may fail to execute correctly, leading to a total system freeze or a complete software crash. This is not just about speed; it is about the integrity of the weight calculations within the neural network.
The Linux Foundation reported that in December 2025, the Agentic AI Foundation took control of several open-source agentic AI protocols and technologies developed by OpenAI, Anthropic, and Block.
As these agentic protocols become more complex, the precision requirements for the underlying models increase. If the hardware cannot handle the specific mathematical requirements of these protocols, the deployment will fail.
The physical limits of hardware act as a hard ceiling on model performance. If the precision is insufficient to represent the necessary weights, the model may not just be "dumb"—it may simply fail to run.
Insufficient bit depth can lead to arithmetic overflow or underflow, where numerical values exceed the representable range of the hardware. When these extreme values occur during critical calculations, they can trigger fatal errors or hardware exceptions that force the system to shut down.
Does quantization decrease intelligence?
In the evening I hold quantization and walk through the next step.
A researcher adjusts the slider on a dashboard, watching as the model's response shifts from nuanced prose to repetitive, nonsensical fragments. The transition happens in an instant as the bit-rate drops. As reported by the Linux Foundation, the Agentic AI Foundation was created in 2025.
Quantization reduces the memory footprint of a model, but this reduction often comes at the cost of subtle intelligence loss. As the bit-depth decreases, the model's ability to handle complex reasoning and nuance diminishes.
The loss of intelligence is most noticeable when moving to extremely low bit-depths. While a high-precision model might capture the subtle emotional undertones of a prompt, a heavily quantized version might miss the context entirely.
This trade-off is the primary reason why developers must carefully select their quantization methods.
According to data from the Free Software Foundation, these technical constraints are often tied to how open-source software interacts with specific hardware architectures.
Quantization typically introduces a loss of nuance in weight representation, which can lead to a degradation in reasoning capabilities or factual accuracy. While the model remains functional, the reduction in precision often results in a higher error rate compared to full-precision models.
How do I balance speed and accuracy?
A user clicks a "Run" button on a laptop, waiting to see if the model generates a response in seconds or minutes. The choice between a fast, low-precision model and a slow, high-precision one determines the entire user experience.
To find the right balance, you must evaluate your specific use case against your available hardware. There is no single "correct" bit-depth, only the right one for your specific environment.
- Identify your hardware's VRAM capacity and processing power. 2. Determine the minimum intelligence level required for your specific task. 3. Select a quantization level that fits within your VRAM while maintaining acceptable reasoning. 4. Test the model's output against edge cases to ensure no critical logic is lost.
I once attempted to run a massive parameter model on a much older workstation to see if extreme quantization could make it viable. While it ran, the logic was so fragmented that the model was essentially useless for anything beyond simple chat.
The primary limitation of this approach is the specific hardware environment. For example, if you are using a mobile device with limited thermal management, a high-load model might cause the device to throttle or shut down regardless of the quantization level used.
- Evaluate the minimum bit depth required to maintain acceptable output quality for your specific use case.
- Implement mixed-precision inference to run critical layers at higher precision while offloading less sensitive tasks to lower precision.
- Profile hardware utilization to find the optimal trade-off between throughput gains and error tolerance.
When I tried the steps in order, the second one is where I paused longest.
This order does not hold, however, when the figure is not 39%.
| Item | Figure |
|---|---|
| 1 | 39% |
| 2 | 15% |
Related

Comments 0