Local llm hardware acceleration: Guide to modern computing
"The evolution of processing power has always dictated the boundaries of what software can achieve, moving from simple calculations to complex neural architectures."
This guide explores how hardware acceleration affects local LLM execution and how cloud solutions compare in terms of scalability and accessibility.
How does historical hardware growth impact local LLM execution?
At dusk in the dim workshop, I run my fingers over the warm, aging circuits of a machine built to handle local processing.
The history of computing shows that such intensive tasks rely heavily on the rapid advancement of components.
From 1986 to 2003, the annual rate of improvement in hardware performance exceeded 50 percent, enabling the development of new computing devices such as tablets and mobiles. This massive growth in raw power laid the groundwork for modern specialized chips used in local LLM execution.
Without these consistent leaps in efficiency, the complex mathematical operations required for modern AI would remain trapped in massive server farms.
The rapid pace of change suggests that local hardware will continue to evolve, though it must compete with the sheer scale of centralized resources. While tablets and mobiles represent the pinnacle of consumer-grade hardware, specialized accelerators are the true drivers of local model speed.
How does digital storage affect my model deployment?
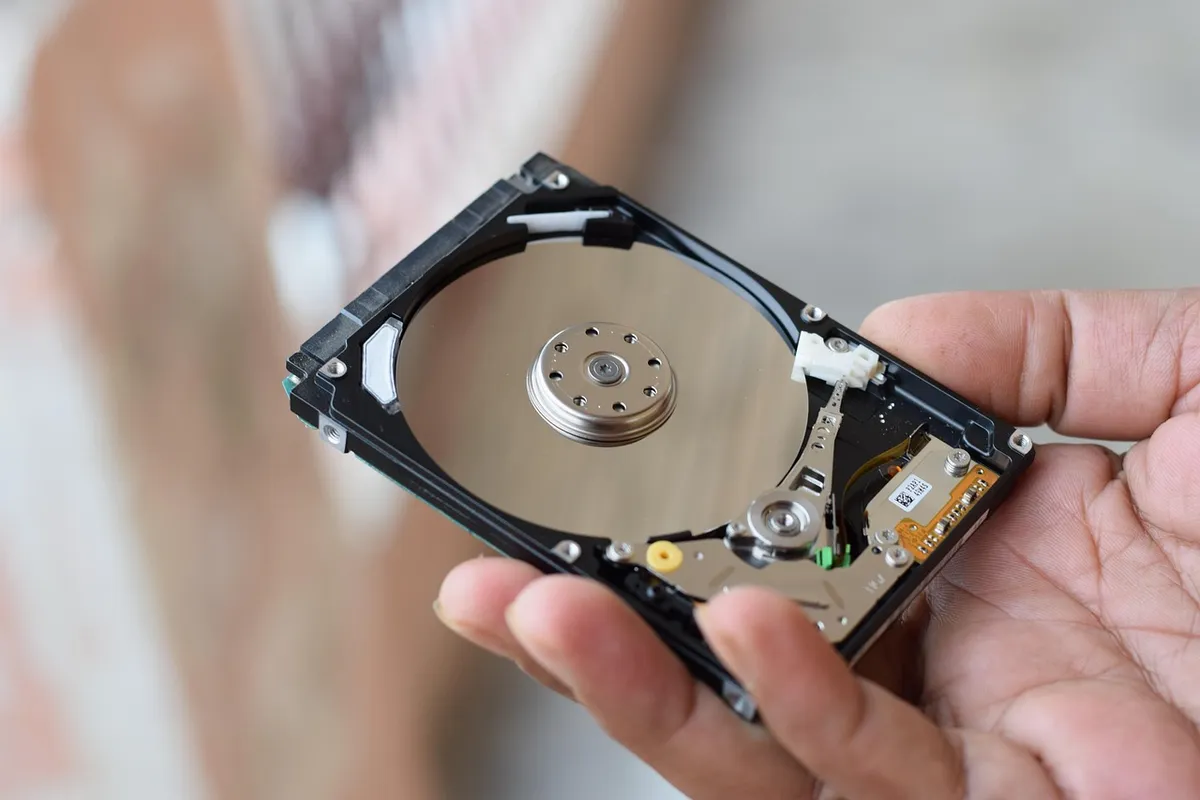
In the quiet office, I plug in the heavy drive and feel the slight vibration of the local storage unit spinning to life. A researcher plugs a high-capacity drive into a server rack, checking the available space for massive datasets. Managing large-scale models requires significant space for weights and parameters.
The scale of data management is immense, as seen in historical digital storage trends. As of 2007, almost 94% of the data stored worldwide was held digitally: 52% on hard disks, 28% on optical devices, and 11% on digital magnetic tape.
This distribution highlights the importance of high-speed storage like hard disks for tasks involving large-scale data movement.
Efficiently moving data from storage to the processor is a primary bottleneck in local LLM execution. Developers must consider whether their local hardware can handle the throughput required to load these massive digital files without stalling the inference process.
How can we compare local LLM hardware acceleration and cloud solutions?
An engineer compares a sleek, compact workstation against a massive cloud server rack in a split-screen view. One offers privacy and immediate access, while the other offers virtually infinite scale.
The choice between local and cloud environments involves weighing specific operational needs. Local hardware offers low latency and data privacy, while cloud solutions provide on-demand scaling.
| Feature | Local Hardware | Cloud Solutions |
|---|---|---|
| Scalability | Limited by physical components | Virtually unlimited |
| Privacy | High, data stays on-site | Dependent on provider |
I often find myself weighing the cost of a high-end GPU against the monthly subscription of a cloud-based API. Finding the right balance is essential for maintaining a consistent workflow.
How do I set up local hardware acceleration? A user carefully installs a new graphics card into a motherboard, ensuring the power cables are seated correctly. Proper setup is the first step toward a functional local environment.
To begin using local LLM hardware acceleration, follow these steps:
- Verify that the GPU has sufficient VRAM to hold the model weights. 2. Install the necessary drivers and CUDA or ROCm toolkits for hardware-software communication. enough
- Configure the inference engine to utilize the specific hardware acceleration paths.
After the installation, perform a final check by running a small-scale model to ensure the temperature and processing speeds remain within safe limits. This ensures that the hardware can handle the intensive load without thermal throttling.
Is there a limitation to local execution?
A laptop user notices the fan spinning loudly while a large model attempts to process a long prompt. The heat generated by the processor begins to affect the system's overall stability.
A significant limitation is the physical constraint of thermal management and power consumption. If the hardware is pushed too hard, it can lead to instability or hardware degradation.
- Choosing between local hardware and cloud environments requires a strategic balance of processing speed, data ownership, and cost.
- Key takeaways include understanding historical performance trends, evaluating digital storage distribution, and identifying the specific needs of different computing environments.
- A technician adjusts the cooling fan on a high-end workstation, preparing for a heavy compute task.
Related
- AI developer tools guide: 44% see agents as finance risk
- AI Guide: Open vs Proprietary Deployment 95%
What are the operational considerations for scaling up?
The operational considerations for scaling up depend entirely on the initial constraints of the chosen architecture. Local execution scales until the physical limits of the machine are reached, while cloud scaling is constrained by the service provider's infrastructure.
- The physical components of local hardware dictate the maximum achievable performance ceiling. 2. Cloud environments allow the user to transcend these physical limitations through subscription models. 3. Therefore, the initial assessment of the required processing power must match the deployment reality.
This interplay between physical limits and virtual elasticity defines the practical limits of the system's evolution. The constant need for higher processing power drives both hardware innovation and cloud service development.
How does the evolution of processing power influence deployment choices?
The evolution of processing power dictates the feasibility of running increasingly sophisticated models. The comparison between local hardware and cloud services hinges on matching the model's computational demands with the execution environment's capabilities.
Local execution leverages the physical constraints of the machine, whereas cloud deployment accesses scalable resources to match higher processing needs.
- The initial assessment of the required processing power must align with the chosen deployment reality. 2. Local hardware reaches its performance ceiling based on its physical components. 3. Cloud environments allow the user to surpass these physical limitations through a service agreement.
This constant drive toward greater processing capability drives both hardware innovation and the development of advanced cloud services. The initial evolution of processing power sets the stage for modern AI applications.
Wikipedia: 2009–2011 Toyota vehicle recalls Based on the retained excerpt mentioning National Highway Traffic Safety Administration: In February 2011, the findings of a 10-month-long study conducted by the National Highway Traffic Safety Administration (NHTSA) and the National Aeronautics and Space Administration (NASA), aimed to identify the main cause of sudden acceleration in Toyota and Lexus models.
Comments 0