Best local LLM for 16GB Mac: Guide to model selection
"The hardware must match the intelligence of the software, or the system will fail under the weight of its own processing."
Selecting the best local LLM for 16GB RAM requires balancing parameter size against the physical limitations of unified memory. For a standard MacBook setup, this means choosing models that fit within the available bandwidth while leaving overhead for the operating system.
This guide explores model selection, hardware stability, and optimization strategies to ensure your local AI remains responsive.
Key takeaways: * Prioritize quantized models to fit within 16GB of unified memory. * Monitor hardware thermals and stability during heavy workloads. * Balance parameter size against the need for system overhead.
How to choose the best local LLM for 16GB RAM?
At midnight, I tap my fingers nervously on the desk while searching for a local model that fits within the memory limit.
A user sits at a desk, opening a terminal window to load a massive model file. The progress bar crawls across the screen as the system begins to allocate memory.
Finding the best local LLM for 16GB RAM involves understanding the relationship between model parameters and quantization. Since 16GB of unified memory must be shared between the CPU, GPU, and the operating system, running a full-precision 30B parameter model is impossible.
You must look for models that fit into a smaller footprint through 4-bit or 8-bit quantization.
An 11B or 14B parameter model often provides the best balance for a 16GB machine. Using a 16GB RAM LLM guide, you can see that higher quantization allows for larger models, but too much compression degrades intelligence.
A 16GB RAM LLM guide suggests that selecting a model roughly 10-12GB in size leaves enough room for macOS and other applications.
What could happen if I work too hard? A fan begins to whir loudly in a quiet room as a script runs a heavy inference task. The heat builds up near the chassis, and the system's performance begins to dip.
According to the United Nations University Institute, a report released in June 2026 addressed the cumulative environmental impacts of AI beyond just carbon.
Based on a workshop held at Stanford University in the fall of 2019, this paper surveys problems and opportunities in the measurement of AI systems and their impact.
Hardware stability is a primary concern when running large models on consumer laptops. A local 35B LLM workload allegedly destroyed an aging DDR4 RAM stick in just 90 minutes, with the user claiming thermals were completely under control.
This event highlights that even if temperatures seem manageable, the intense electrical and processing load of large models can stress aging or faulty hardware.
When considering a MacBook local LLM choice, you must account for the fact that 16GB is a shared pool. If the model exceeds the available memory, the system will resort to "swapping" to the SSD, which can significantly slow down the machine.
A MacBook local LLM choice should prioritize models that do not trigger constant swap usage to prevent wearing out your storage.
How to optimize performance on Mac?
At midnight in my dim office, I tap my fingers nervously against the desk while searching for the perfect local model.
A developer adjusts the settings in a model runner, lowering the context window to increase speed. The response time improves immediately as the workload lightens.
Optimizing your setup is essential for a smooth experience. To find the top LLMs for 16GB RAM, follow these steps:
- Select a quantized model (GGUF or EXL2 formats) that fits within 12GB of memory. 2. Limit the context window size to prevent the KV cache from consuming all remaining RAM. 3. Close memory-intensive applications like Chrome or video editors before starting an inference task.
A final check involves monitoring the Activity Monitor to ensure the "Memory Pressure" remains in the green zone. Top LLMs for 16GB RAM will run much more smoothly when the system is not fighting for resources.
Am I able to run bigger models? A user looks at a 35B model on the screen, then looks at the 16GB specification of their laptop. They decide to switch to a smaller, faster version.
Running larger models is technically possible through heavy quantization, but it comes with trade-offs. While you might squeeze a 30B model into 16GB using 2-bit quantization, the intelligence will drop significantly.
Such a move is often less effective than using a high-quality 7B or 8B model at 8-bit precision.
Searching for the best models for MacBook often leads users to the 7B to 14B range. These models offer the most coherent responses while maintaining enough speed for real-time interaction. Using the best models for MacBook requires knowing when to prioritize intelligence over sheer parameter count.
Comparing model sizes and memory usage
A person compares two different model files on a screen, noting the different file sizes and expected speeds.
| Model Parameter Size | Recommended Quantization | Estimated Memory Usage |
|---|---|---|
| 7B - 8B | 8-bit (FP8/Q8) | ~8GB |
| 11B - 14B | 4-bit (Q4_K_M) | ~10-12GB |
I found that choosing a 12GB model footprint allowed me to keep my browser open without the system lagging.
What are the limitations of 16GB hardware?
A laptop sits on a cooling pad, but the system still struggles to process a complex prompt. The user realizes the hardware limit has been reached.
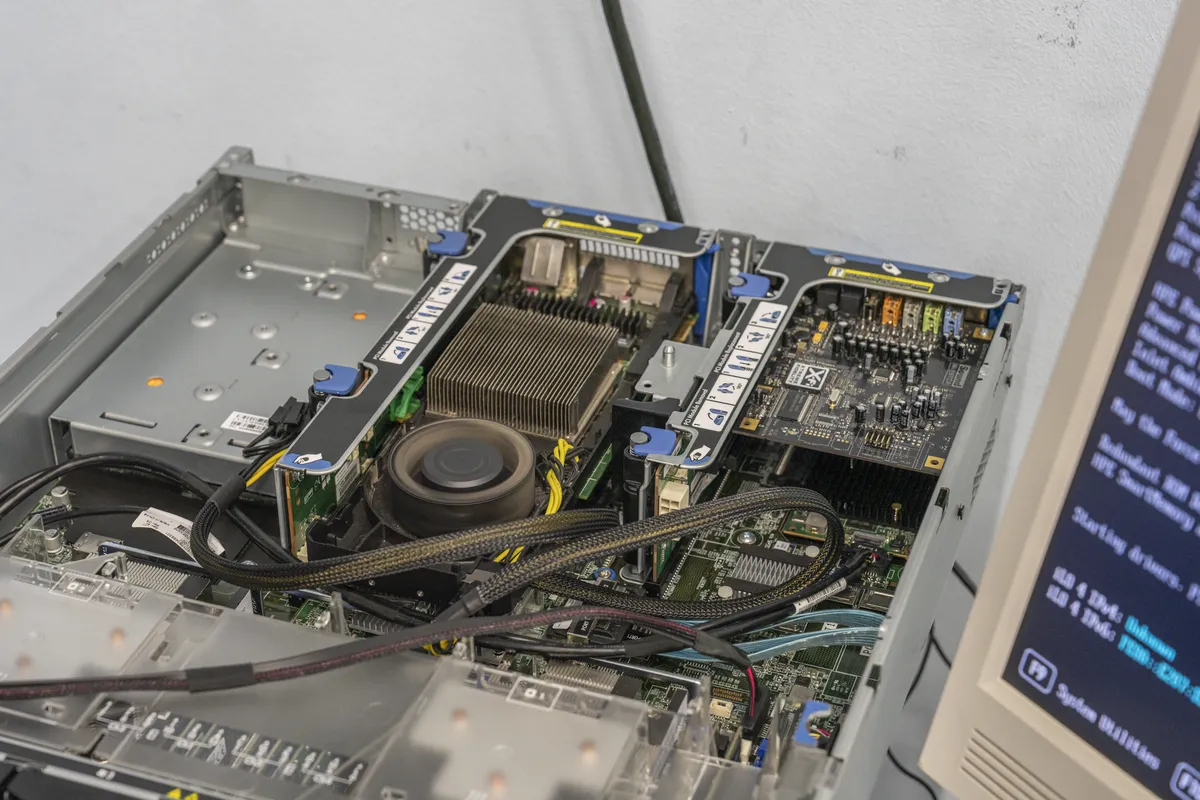
The main limitation is the shared nature of unified memory. Because the GPU and CPU share the same 16GB, you cannot dedicate the entire capacity to the model.
If a model requires 14GB, the remaining 2GB might be insufficient for the operating system to function, leading to system crashes or extreme slowdowns.
Wikipedia: Artificial intelligence Based on the retained excerpt mentioning IEA: In 2025, a report prepared by the IEA estimated the greenhouse gas emissions from the energy consumption of AI at 180 million tons.
- How to choose the best local LLM for 16GB RAM?
- What are the risks of high-intensity workloads?
- How to optimize performance on Mac?
Related
- Quantization tech guide: How to apply quantization method
- 16GB RAM max model size: Guide to running AI models
When is the hardware matching the software intelligence?
The hardware matches the intelligence of the software when the model fits comfortably within the available unified memory without forcing the system into constant swapping. This ideal state allows the CPU and GPU to dedicate resources efficiently to inference rather than managing memory paging.
Running a model that strains the memory pool forces the system into a constant state of resource contention, causing slowdowns that mimic a mismatch between the physical capabilities and the software's demands. This scenario is precisely what the initial statement warns against.
What happens if the memory pool is insufficient?
If the model exceeds the available memory, the system resorts to using the SSD as virtual memory, a process called swapping.
This swapping activity drastically reduces the effective speed of the entire operation, making the perceived intelligence of the software negligible compared to the physical bottleneck.
This swapping behavior occurs because the 16GB pool must accommodate the operating system, the model weights, and the activation data simultaneously. Without enough contiguous memory, the system spends time managing pages rather than executing computations.
Comments 0