LLM for 16GB RAM: Guide to model selection and performance
"Running a large language model on a machine with limited resources requires a delicate balance between parameter count and quantization levels."
Finding the right LLM for 16GB RAM involves selecting a model size that fits within the available VRAM or unified memory while leaving enough overhead for the operating system.
This guide focuses on selecting models that prevent system slowdowns, understanding how quantization affects performance, and identifying the best parameter ranges for this specific memory capacity.
Key takeaways: 1. Prioritize models in the 7B to 14B parameter range for stable performance. * Use 4-bit or 8-bit quantization to fit larger models into 16GB of memory. * Account for system overhead to avoid heavy swapping or crashes.
How to choose an LLM for 16GB RAM?
A developer sits at a desk, staring at a terminal window where a model is loading. The fan whirs loudly as the memory usage climbs toward the 16GB limit. According to the Allen Institute, the Allen Institute for AI released an open-source vision-language model in 2024.
Selecting the best model 16GB setup requires looking at the total memory footprint of the model weights plus the KV cache.
For a 16GB system, a 7B or 8B parameter model at 8-bit quantization usually runs smoothly, while a 14B model at 4-bit quantization provides a tighter but more capable experience. If you push toward 30B models, the system will likely rely on much slower swap memory, leading to unusable speeds.
The goal is to ensure the model fits entirely within the available memory to maintain high tokens-per-second. If the model size exceeds the physical limit, the performance drop is immediate and severe.
What does model size vs memory mean in practice?
At his desk in the dim office, the user watches the task manager graph climb as the heavy model begins to process.
A user opens a task manager on a laptop to check the current memory pressure. The graph shows a steady climb as the model processes a long prompt.
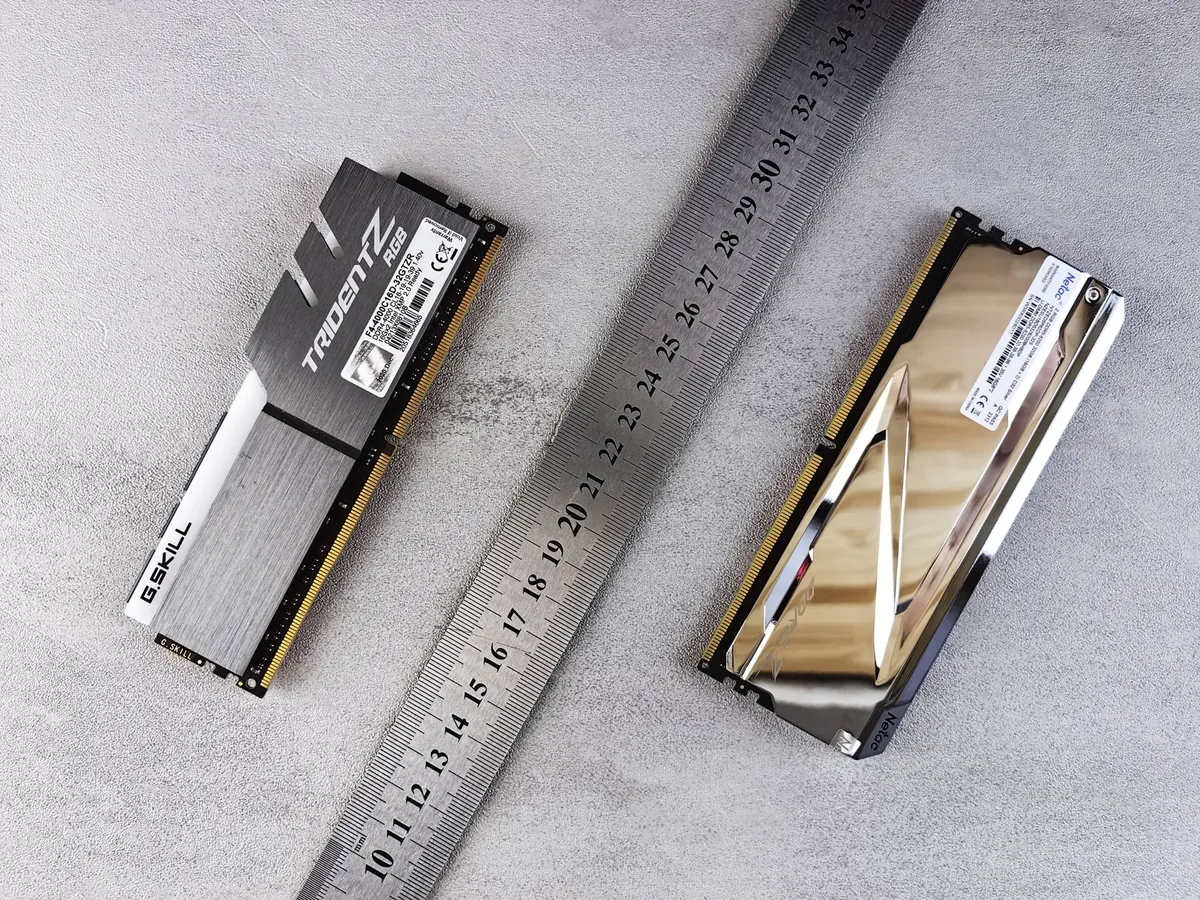
Understanding model size vs memory is about calculating the gigabytes required for the weights. A 7B model using 4-bit quantization takes roughly 5GB of space, leaving plenty of room for the OS and context.
However, a larger model might fit the weights but fail once the context window grows, as the KV cache also consumes significant memory.
The relationship between parameters and memory is not linear because quantization changes the math. You must ensure that the peak memory usage, including the context, does not exceed your 16GB capacity.
How to run LLM limited mem setups effectively?
An engineer adjusts the quantization settings in a local inference tool. They switch from a heavy 16-bit version to a lighter 4-bit version to regain responsiveness.
To run LLM limited mem environments, you must use quantization techniques like GGUF or EXL2. These methods compress the weights to reduce the memory footprint without destroying the model's intelligence.
A common strategy is to use a smaller, highly optimized model rather than a larger, heavily compressed one.
Follow these steps to manage your local setup: 1. Select a model with a parameter count between 7B and 14B. 2. Apply 4-bit or 5-bit quantization to keep the weight footprint low. 3. Monitor the memory overhead to ensure the OS has at least 2-4GB of free space.
I found that choosing a 7B model with high-quality quantization was much more productive than struggling with a 30B model that caused constant system lag.
What are the small LLM performance trade-offs?
A researcher compares two side-by-side screens, one running a large model and the other a small model. The small model responds instantly, while the large one stutters.
When looking at small LLM performance, the primary trade-off is intelligence versus speed. Smaller models are incredibly fast and fit easily into 16GB, but they may struggle with complex reasoning or long-form creative writing.
However, for tasks like summarization or basic coding assistance, a well-tuned 8B model often provides the best utility.
It is often better to have a fast, reliable small model than a slow, crashing large one. This balance is the key to a functional local workflow.
How to manage a 16GB LLM setup guide for different tasks?
A writer types a prompt into a chat interface, watching as the text flows steadily across the screen. The task is a simple translation, and the model handles it effortlessly.
A 16GB LLM setup guide should prioritize task-specific models. For coding, a model with strong logic like a Llama-based derivative is excellent. For creative writing or chat, a model with better prose capabilities might be preferred.
Because memory is the bottleneck, you can often run a slightly larger model for "thinking" tasks and a smaller one for "chatting" tasks.
| Model Size | Recommended Quantization | Typical Use Case |
|---|---|---|
| 7B - 8B | 8-bit (Q8) | General purpose, high speed |
| 13B - 14B | 4-bit (Q4_K_M) | Complex reasoning, better logic |
A limitation of this setup is that running a 14B model at 4-bit quantization may limit the available context window size on a 16GB machine.
- How to choose an LLM for 16GB RAM?
- What does model size vs memory mean in practice?
- How to run LLM limited mem setups effectively?
The subject here is LLM for 16GB RAM.
The same subject is also called memory fit llm.
Related
- Local llm hardware acceleration: Guide to modern computing
- AI developer tools guide: 44% see agents as finance risk
What are the risks of pushing the memory limits?
If the machine attempts to run a model larger than what 16GB can comfortably hold, the system will begin swapping heavily to disk. This swapping process causes the tokens-per-second rate to plummet, rendering the running large language model nearly unresponsive.
The operating system must manage this constant data movement between fast RAM and slow storage.
This scenario arises when the combination of weights, activations, and the KV cache exceeds the physical memory boundary. The immediate consequence of exceeding this boundary is a severe performance degradation, making the interaction frustratingly slow.
Therefore, the initial selection of the model size must account for the dynamic memory needs during generation, not just the static weight size.




Comments 0